Today’s large language models can solve Olympiad-level math problems, pass professional exams, and write complex code. Yet in real-world applications, they often fail—spectacularly. So where exactly does the problem lie?
In the first paper he published after joining Tencent, Yao Shunyu offered a sharp diagnosis of this phenomenon:
“The gap between today’s AI systems and true intelligence is not about how much knowledge they possess, but about their ability to learn. An AI stuffed with knowledge but incapable of learning is like someone who has memorized an entire dictionary yet cannot write. It may look knowledgeable, but it is fundamentally rigid.”
The paper is titled “CL-bench: A Benchmark for Context Learning.”
What Is CL-bench?
CL-bench is a large-scale benchmark designed specifically to evaluate context learning ability in language models. Its full name, Context Learning Benchmark, makes this focus explicit.
The benchmark includes:
All tasks were carefully designed and selected by senior experts across multiple domains.
The core design principle of CL-bench is simple but radical:
This paper not only exposes a fundamental weakness in current AI systems, but also introduces a new evaluation framework tailored specifically to AI. It is essential reading for anyone working on large models or AI agents.
A Mirror That Exposes AI’s “Fake Learning”
On average, each context in CL-bench contains 3.8 tasks, with some contexts including up to 12 tasks.
More importantly, 51.1% of the 500 scenarios contain sequential dependency.
In these cases, later tasks can only be solved if earlier ones are answered correctly. This multi-step interaction design dramatically increases difficulty.
Each task requires an average of 20 hours of expert annotation, and is evaluated using 16.6 distinct criteria, covering:
The benchmark is not testing how much knowledge an AI has memorized.
It is testing whether an AI can do what humans do every day: learn from new material and use it correctly.
All tasks share one defining feature:
the model must learn on the fly to pass.
Pretrained knowledge is largely useless here, because the content in CL-bench is either:
The paper verifies this through ablation experiments.
When the contextual information is removed, all tested models solve fewer than 1% of the tasks.
This conclusively demonstrates that success depends almost entirely on learning from context.
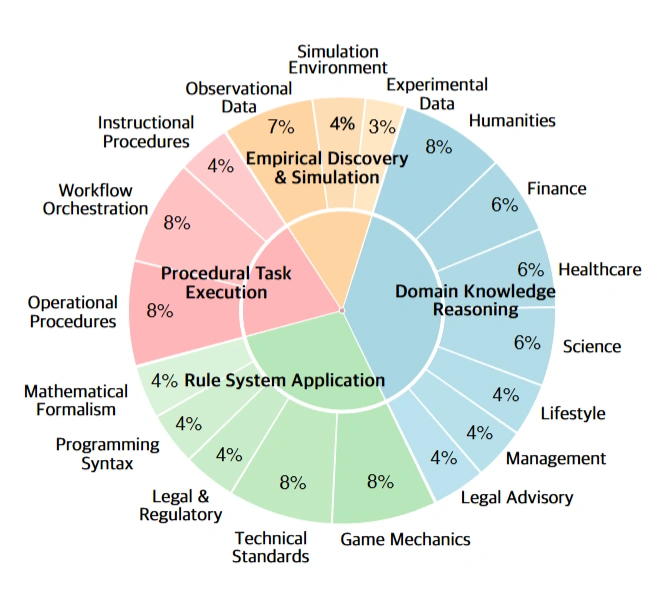
CL-bench divides tasks into four major categories, each corresponding to a distinct cognitive demand:
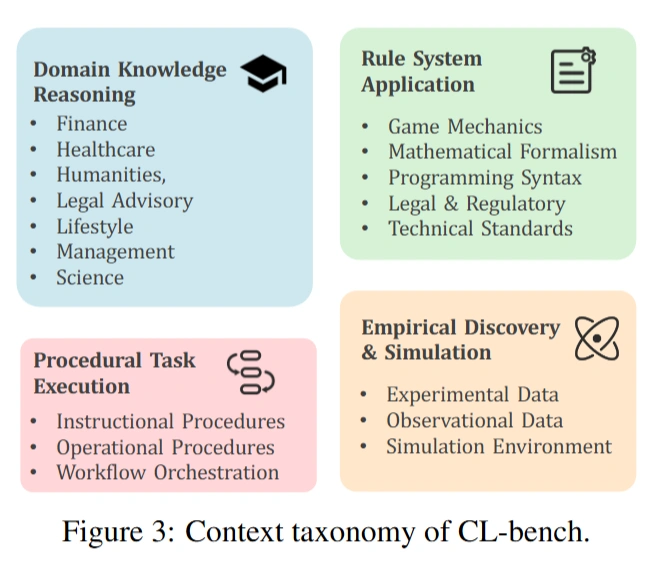
1. Domain Knowledge Reasoning
Covering finance, medicine, humanities, legal consulting, lifestyle, management, and science.
The context provides specialized domain knowledge—such as a fictional legal system, novel financial instruments, or obscure professional expertise. The model must learn and apply this knowledge to reason correctly.
Example: providing a complete legal code and case law for a fictional country, then asking the model to adjudicate a complex civil dispute.
2. Rule System Application
Including game mechanics, mathematical formal systems, programming languages, legal regulations, and technical standards.
Here, the context defines a formal rule system that the model must strictly follow.
Examples:
3. Procedural Task Execution
Divided into instructional procedures, operational procedures, and workflow orchestration.
The context provides complex workflows, manuals, or operational processes. The model must learn and execute them correctly.
Example: given a ~7,000-word API document for a drone logistics system, convert natural-language instructions into safe, compliant pseudocode.
4. Empirical Discovery & Simulation
The most challenging category, including experimental data, observational data, and simulated environments.
Unlike the first three categories, which emphasize deductive reasoning, this category requires inductive reasoning—discovering patterns from data or making decisions in simulated environments.
Example: given 300 experimental logs of charged particles moving in a magnetic field, infer the governing laws and compute specific parameters.
Together, these four categories cover most real-world learning scenarios humans encounter at work. CL-bench effectively brings real-world learning into the evaluation framework.
Put simply:
Humans use these abilities daily. AI clearly does not—yet.
To ensure the benchmark tests learning rather than recall, CL-bench employs a strict anti-contamination strategy:
1. Fully Fictional Content
All test materials are entirely original.
For example, a fictional country is created with its own constitution, civil law, criminal law, and case precedents—none of which resemble any real legal system.
Or a new educational programming language called EduScript is invented, complete with unique syntax and control structures.
2. Systematic Modification of Existing Knowledge
Real-world knowledge is deliberately altered:
historical causal relationships are changed, physical laws are rewritten mathematically, and technical standards are modified.
Even if a model has seen something similar, it cannot reuse pretrained knowledge directly.
3. Integration of Niche and Emerging Content
CL-bench also includes material rarely found in training data, such as:
The goal is singular: prevent shortcuts.
The model cannot rely on memorization—it must learn in real time.
Ablation results confirm the effectiveness of this design: without context, even GPT-5.1 solves fewer than 1% of tasks.
Results That Are Both Encouraging and Disturbing
The evaluation criteria are unforgiving.
Each task is judged across multiple binary dimensions—pass or fail, with no partial credit. A single mistake causes the entire task to fail.
The scoring checks:
Only if all criteria pass does the task count as solved.
To validate the reliability of automated grading, the paper used:
1. Five different AI models as judges, achieving over 90% agreement
2. Manual review of 200 samples, also exceeding 90% accuracy
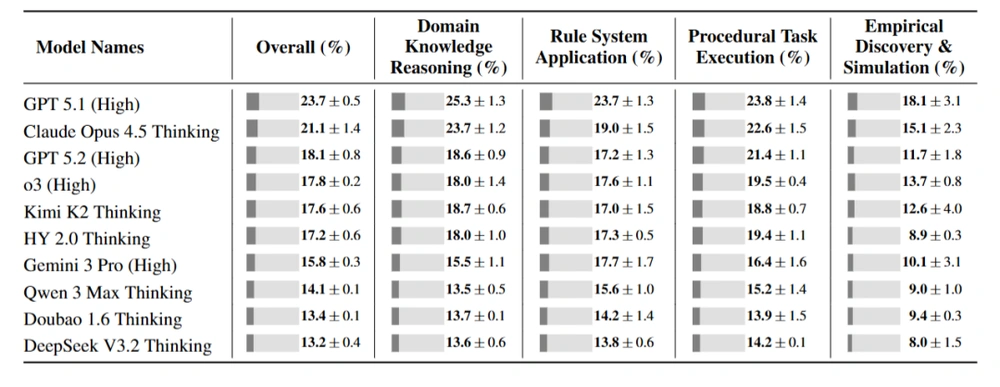
Across ten state-of-the-art models, the average task completion rate is only 17.2%. The best-performing model, GPT-5.1, reaches just 23.7%.
In other words, even when all necessary information is provided, models fail most of the time.
That number deserves reflection. A 23.7% success rate means that even with a complete manual, the AI fails three out of four times.
In real life, an employee with this performance would not last long.
Error analysis reveals three dominant failure modes:
These errors point to a deeper issue:
A student who cannot see, think, or listen cannot learn.
The findings reveal a long-overlooked truth:
today’s AI models are parameter reasoners, not context learners.
They excel at retrieving static knowledge compressed into weights, but struggle to acquire new knowledge dynamically from input.
This explains why models perform well on standardized tests yet fail in real-world tasks.
They are like someone who has memorized an entire dictionary. Ask them how to spell a word, and they succeed. Give them a new book to learn from, and they freeze.
Implications
CL-bench fills a critical gap in existing evaluation frameworks.
Previous long-context tests focused on information retrieval. Instruction-following benchmarks tested obedience, not learning. Domain benchmarks conflated retrieval and application.
CL-bench isolates one capability: learning from context and applying what was learned.
It also reveals counterintuitive findings. For instance, GPT-5.2 performs 5.6% worse than GPT-5.1 on this benchmark, struggling to maintain causal coherence and frequently violating contextual constraints.
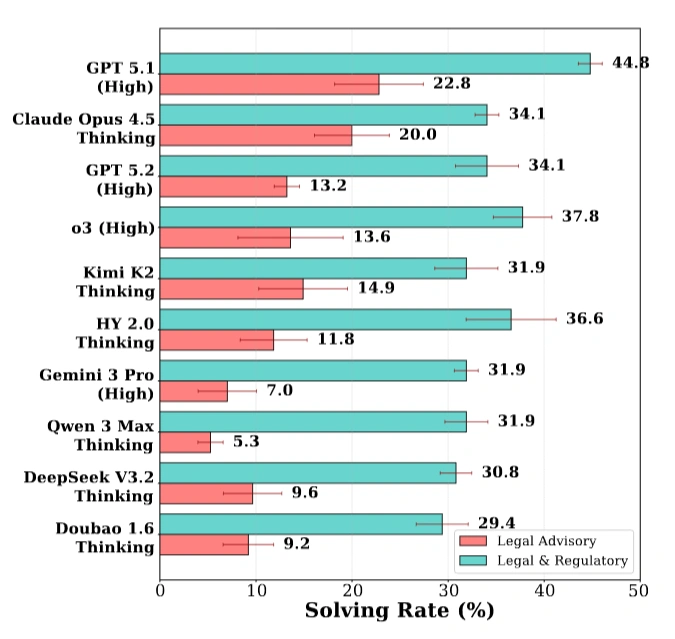
More reasoning does not always help. Without the right learning mechanism, “thinking harder” only amplifies errors.
The Bigger Picture
The problem exposed by CL-bench is not just technical—it is paradigmatic.
We have optimized AI for reasoning over the known, but real-world tasks demand adaptation to the unknown.
Without learning ability, AI—no matter how powerful—remains an advanced query system.
With true learning ability, it can evolve from a tool into an agent.
CL-bench suggests that the future of AI lies not in larger models or more parameters, but in stronger learning mechanisms.
And context learning, it turns out, is only the beginning.
Editor: Zhongxiaowen